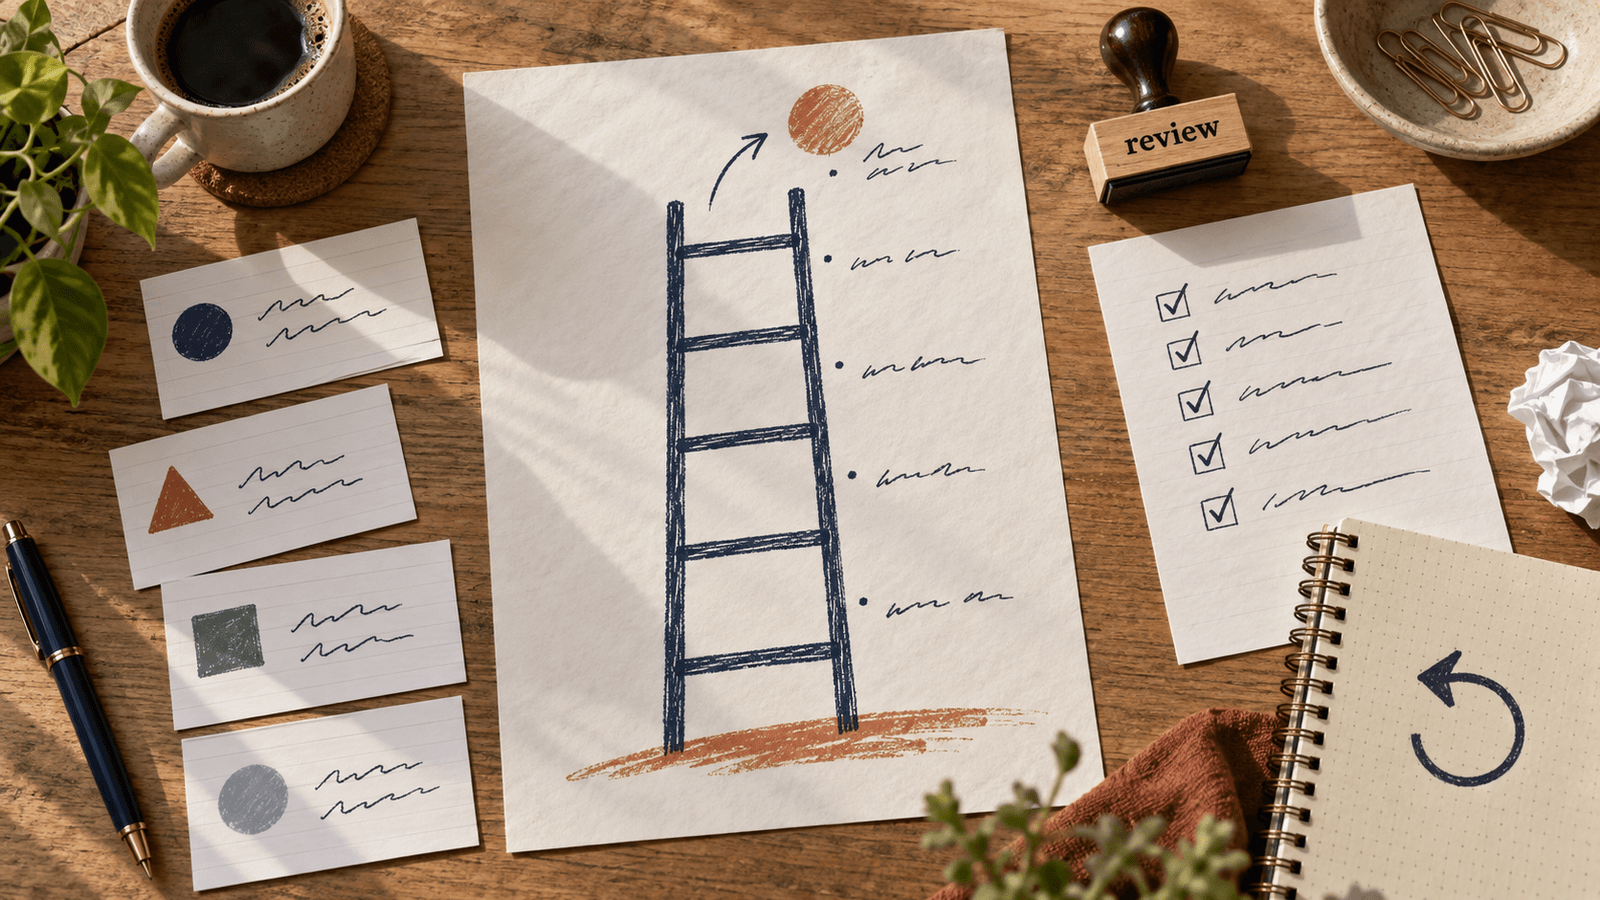

Most automation conversations begin one rung too high.
The request sounds reasonable: this task happens every week; surely a system can take it over. Then the work moves from a person’s head into a tool configuration, and the missing bits arrive at the least charming possible moment.
The missing bits are decisions: which input counts, what “done” looks like, what to do with an exception, and who gets to say no.
There is plenty of public context for slowing down before declaring every workflow ready for automation. Statistics Canada reported that 12.2% of businesses had used AI to produce goods or deliver services in the 12 months before its second-quarter 2025 survey. Among those businesses, developing new workflows was the most commonly reported operational change after implementation. That does not tell us what any one team should build. It does suggest that the workflow deserves attention alongside the tool.
OpenAI Academy, which is first-party vendor guidance rather than independent research, makes a useful narrower distinction: agent-style workflows are most useful when work is repeatable, structured, time- or event-based, and connected to approved tools. Open-ended thinking and one-off exploratory work are a different shape of problem.
So here is a deliberately unglamorous way to decide what comes next: climb one rung at a time.
This five-rung ladder is an editorial synthesis, not a certification, professional advice, or a guarantee. Its job is to make a workflow legible before it becomes ambitious.
Rung 1: Do the work manually — and record the decisions
Manual does not mean unstructured. It means a person completes the task while writing down the choices that keep it from going off the rails.
Imagine turning public event notices into a short internal briefing. For the first few runs, record source locations, inclusion rules, the output format, and awkward cases: duplicate notice, tentative date, missing second source. Those notes are the workflow.
A useful record is short enough to survive contact with a busy Tuesday. It might include:
- what starts the task;
- what inputs are acceptable;
- the decisions a person makes;
- the output and its audience; and
- exceptions and what happened to them.
If the task cannot be explained after a few manual passes, automating it will not make it clearer. It will merely make the confusion arrive on a schedule.
Rung 2: Standardize the inputs and define “done”
Before connecting anything, make the starting line and finish line boringly specific.
Standardized inputs are not necessarily a grand database project. A shared form, a required set of fields, a predictable folder, or a simple naming convention can be enough. The point is that the person doing the work is not decoding a new puzzle each time.
Then write a definition of done. For the briefing example, “done” could mean: each item has a public source link, an event date if available, a one-sentence summary, a label for uncertainty, and a named reviewer. It does not mean “looks about right.”
This rung earns its keep because it reveals disagreement early. If two capable people would produce meaningfully different outputs from the same input, the standard is unfinished. That is a process question, not a prompt-writing contest.
Rung 3: Automate retrieval or a draft — not judgment
Now the tool can take a constrained first pass.
Good candidates are mechanical retrieval and a labelled draft: collect items from specified public pages, fill a template, flag missing dates, or prepare a summary for review. The output remains a proposal, not a verdict.
A tool may surface “possible duplicates,” but a person decides whether two notices describe the same thing. It may draft a category, but a person decides whether it fits.
Keep the output inspectable. Preserve input links and mark unknowns instead of filling them with confidence-shaped fog. If the draft is hard to compare with its sources, it has created a review problem.
Rung 4: Add named-owner review
Every workflow that reaches beyond a personal scratchpad needs a person whose review is explicit, not implied.
“Someone will look at it” is not an ownership model. Name the role or individual responsible for checking the output, define what they are checking, and decide what sends the work back for correction or escalation.
For a routine public-information briefing, the reviewer might verify source links, dates, duplication flags, and the wording of any caveat. The review does not have to be theatrical. It has to be real enough that a questionable output can stop.
Named review also clarifies a useful boundary: automation can prepare work; accountability does not evaporate because a tool touched it first.
Rung 5: Permit bounded action only with rollback and logs
The top rung is not “fully automatic.” It is bounded action.
Only after the earlier rungs are stable should a system take a limited action: create a draft record, add an item to a review queue, or update a non-public working list. The action should have a narrow scope, a clear permission boundary, a rollback path, and a log that says what happened and when.
Start with a low-consequence action. Avoid making a tool the final sender, publisher, approver, or irreversible editor simply because it can reach that button. If an action cannot be undone or understood afterward, it has not earned this rung.
The test for staying manual
Here is the cleanest test: stay manual when the work is infrequent, inputs vary widely, the definition of done is disputed, exceptions dominate, or a wrong action would be difficult to reverse.
Also stay manual when the real value is human judgment: prioritizing ambiguous trade-offs, handling sensitive context, or thinking through a novel question. That is not a failure to modernize. It is an accurate description of the job.
A practical review question is: could a new person follow the recorded decisions, using standardized inputs, and produce an output a named reviewer can reliably assess? If the answer is no, return to an earlier rung. If the answer is yes, make the next step small and observable.
The ladder is intentionally less exciting than a big reveal. That is its advantage. You do not need to predict whether a workflow deserves a grand automated future. You only need enough evidence to justify the next rung.
Sources
- Statistics Canada, “Analysis on artificial intelligence use by businesses in Canada, second quarter of 2025” — official/public data; published June 16, 2025; accessed September 12, 2026.
- OpenAI Academy, “Workspace agents” — first-party vendor guidance; published April 9, 2026; last updated September 4, 2026; accessed September 12, 2026.