
The warning said almost out of memory. I looked at RAM, because that is what that sentence usually means.
RAM still had gigabytes free.
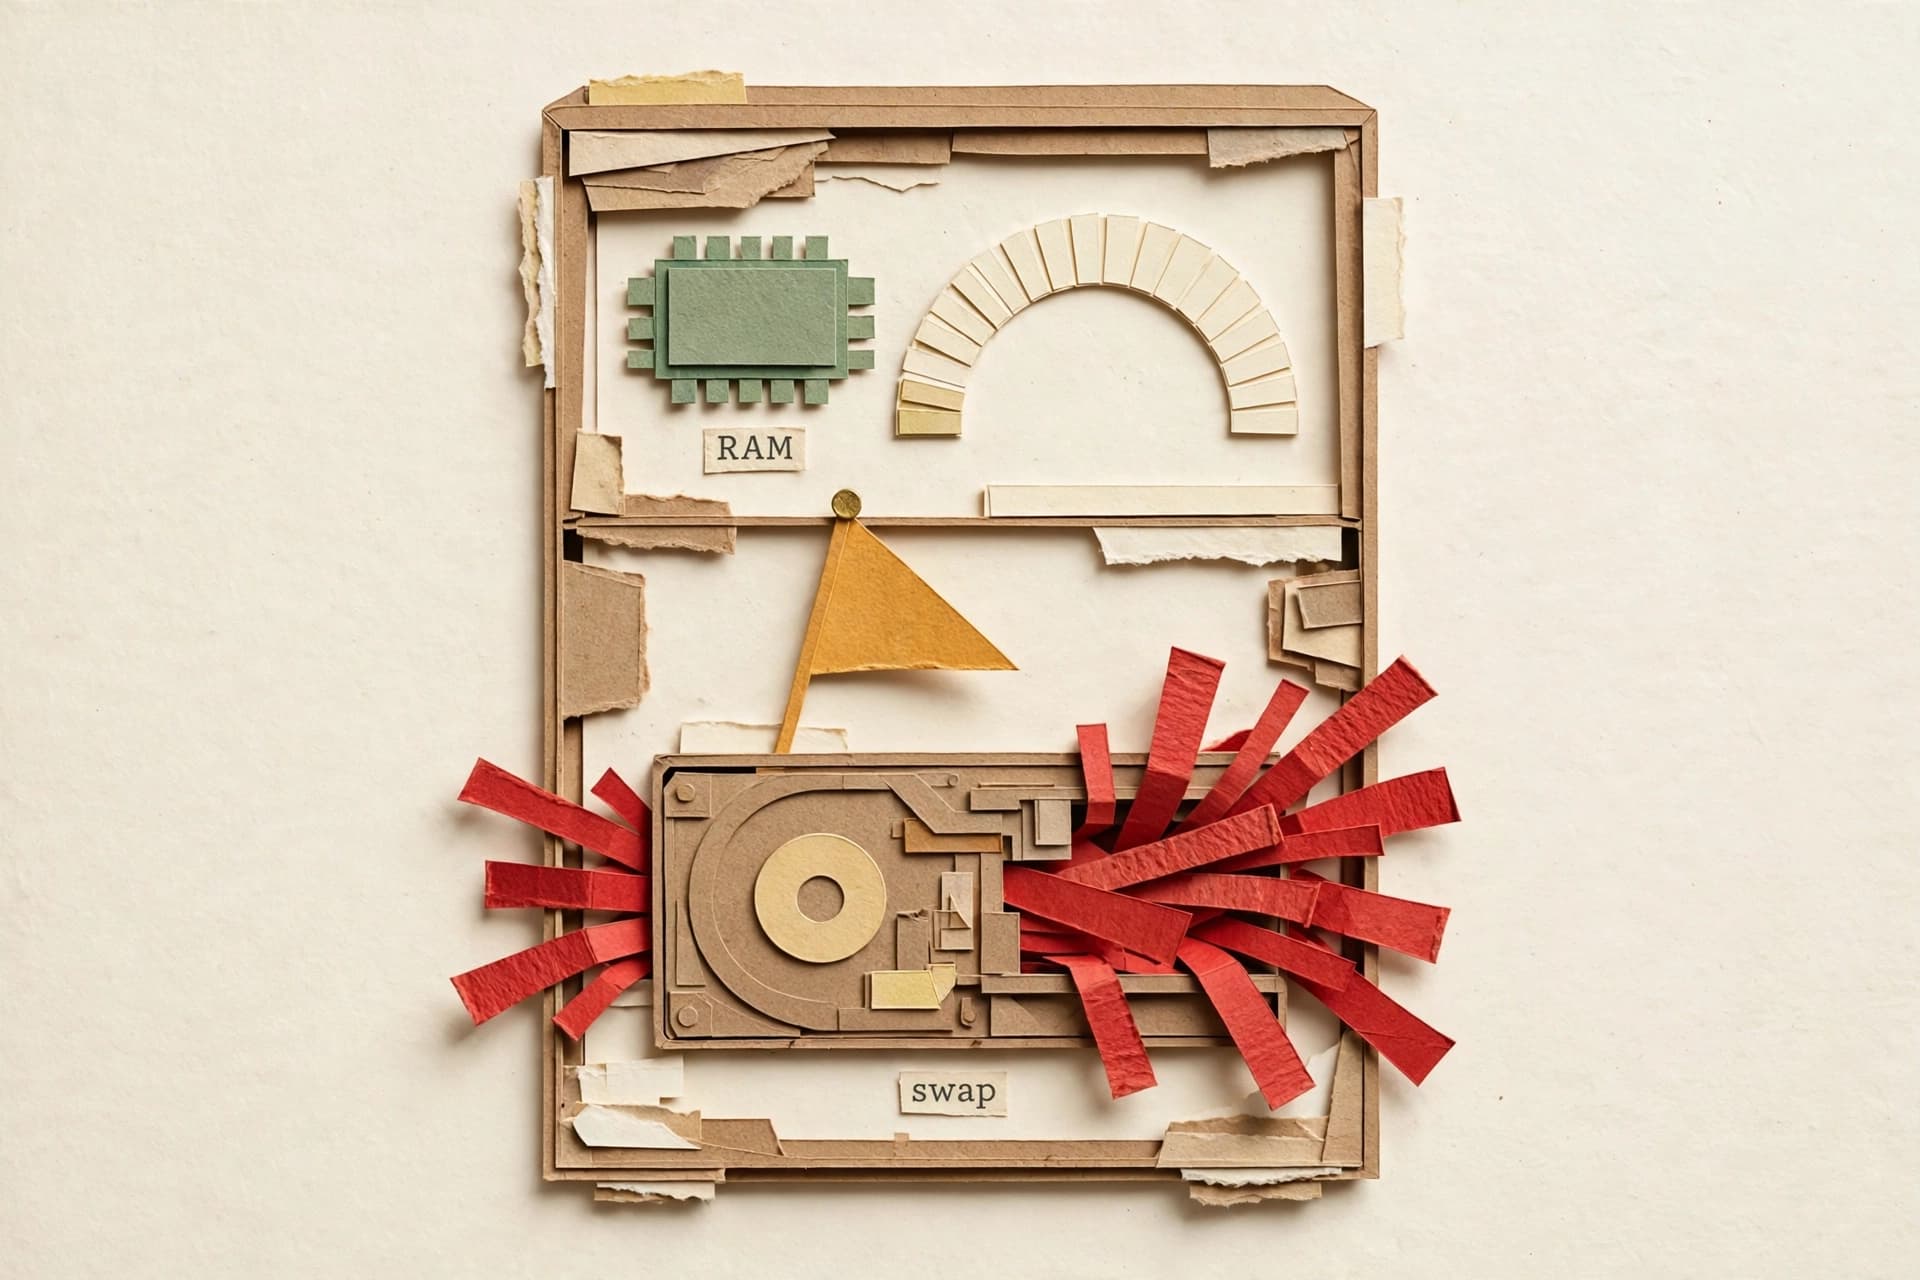
That mismatch is the whole post. The warning was real. It was not “this box has no RAM left.” Swap was already under pressure, and the kernel’s committed address space was larger than physical RAM. Later the same night, swap was full. Isolated morning jobs then failed with a setup timeout before they even started — the same string, across different models.
The useful reading is narrow. A low-memory warning can be swap pressure, not RAM hitting zero. And a full swap can stall new work even when free RAM still exists.
The field that answers the wrong question
When I say “memory” out loud, I mean RAM. Linux does not.
/proc/meminfo has several answers, and they are not interchangeable. The one people treat as leftover room is MemAvailable. The Linux proc_meminfo man page — man-pages 6.19, dated 2026-02-08 — is blunt about what that number is. Since Linux 3.14, MemAvailable is an estimate of how much memory is available for starting new applications without swapping.
It is not a swap-usage gauge.
That distinction sounds fussy until a warning fires. If swap is filling, MemAvailable can still look healthy. Starting something new without swapping is a different question from “is the machine already leaning on swap.” I had been answering the first question and calling it the second.
Swap has its own pair:
SwapTotal— how much swap the machine hasSwapFree— how much of that swap is unused
Glance only at free RAM, and you can miss the part of the story that is already happening on disk. That night, RAM still had gigabytes free while swap was already under pressure. The “almost out of memory” flag was pointing at a different layer than I expected.
Commit is a promise, not a pile of chips
The other field that mattered was Committed_AS.
The same man page describes it as memory presently allocated or committed, including allocations that have not been touched yet. That number can exceed physical RAM. That is not a bug in the accounting. Virtual memory is allowed to promise more than it currently has sitting in chips.
Next to it sits CommitLimit, the overcommit ceiling. Whether that ceiling is actually enforced depends on vm.overcommit_memory. Kernel overcommit docs list three modes:
- 0 — heuristic overcommit, the default
- 1 — always overcommit
- 2 — don’t overcommit: total commit may not exceed swap plus a configurable share of RAM, default 50%
CommitLimit is adhered to only in mode 2. I am not going to pretend I know which mode this host was in. I did not treat that as a fact I had, and claiming mode 2 would make the story tidier than the evidence.
The kernel also accounts and checks commit on fork. That is the part that connects “the RAM graph still looks fine” to “why can’t this new job start?” A new process is a commit event. If the machine is already short on useful headroom, startups can fail or stall even while some RAM still looks free.
Committed_AS larger than RAM is not automatically fatal. Default mode 0 only refuses obvious overcommits. Mode 2 refuses allocations past CommitLimit. Full swap can thrash startups without being a documented “swap error code.” The honest version is a host-resource reading, not a kernel panic with a neat label: new work can fail or stall under commit and swap pressure while some RAM still looks free.
The jobs never reached the runner
The next morning, isolated jobs failed with:
cron: isolated agent setup timed out before runner start
I saw that string on several models the same morning swap was full. That is a tempting moment to start editing the job, the model, or the timeout I configured. It is the wrong first question.
OpenClaw’s automation docs describe that exact string as a setup/startup watchdog. Automations run inside the Gateway process. Those watchdogs are capped independently of a long timeoutSeconds, so cold-start, auth, and context failures surface quickly. The scheduler’s 60-minute watchdog is a run deadline. It is not this setup-phase timeout.
The CLI docs make the same split. Disabling the scheduler wall-clock ceiling with --timeout-seconds 0 still leaves agent/provider timeouts, startup watchdogs, and command-runner limits in effect. Stretching the run timeout does not buy a slower boot.
I am not going to claim that full swap is a documented OpenClaw error code, or that it is the only cause of that string. The official pages name cold-start, auth, and context failures. They do not name swap. What I have is a homelab reading I take seriously: swap was full, several models hit the same setup timeout, and the timeout is a startup watchdog rather than a model failure.
That is enough to change the order of operations. Check the host before rewriting the job.
Two questions, not one dashboard
I do not need a capacity-planning lecture for a personal Linux box. I need a boring order of questions:
- Does RAM still have room, or am I staring at
MemAvailableand calling it the whole story? - What do
SwapTotalandSwapFreesay? - Is
Committed_ASlarger than physical RAM, and am I treating that as interesting rather than automatically fatal? - If a scheduled job died before the runner started, is this a setup watchdog or a run timeout?
The useful mental model is two different questions:
- Can I start something new without swapping? That is
MemAvailable. - Is swap already doing the work RAM could not? That is
SwapTotalversusSwapFree.
Mixing those two is how “almost out of memory” becomes a RAM story when it is a swap story.
This was not a disk-full incident, and it was not a swap-partition resize. The running machine still had RAM. New isolated work still could not get through the door.
The small rule I am keeping
If a home server says it is almost out of memory, I look at swap before I look for a clever software explanation.
If an isolated job times out before the runner starts, I look at host resources before I look at the model name.
Neither of those rules required a reboot tutorial or a claim that Linux always dies when Committed_AS exceeds RAM. They required reading the fields that actually answer the question.
Free RAM is not permission to start new work. Sometimes it is just leftover room on the wrong side of the ledger.